Codex vs Claude Code: I Gave Both the Same Prompt. The Result Surprised Me
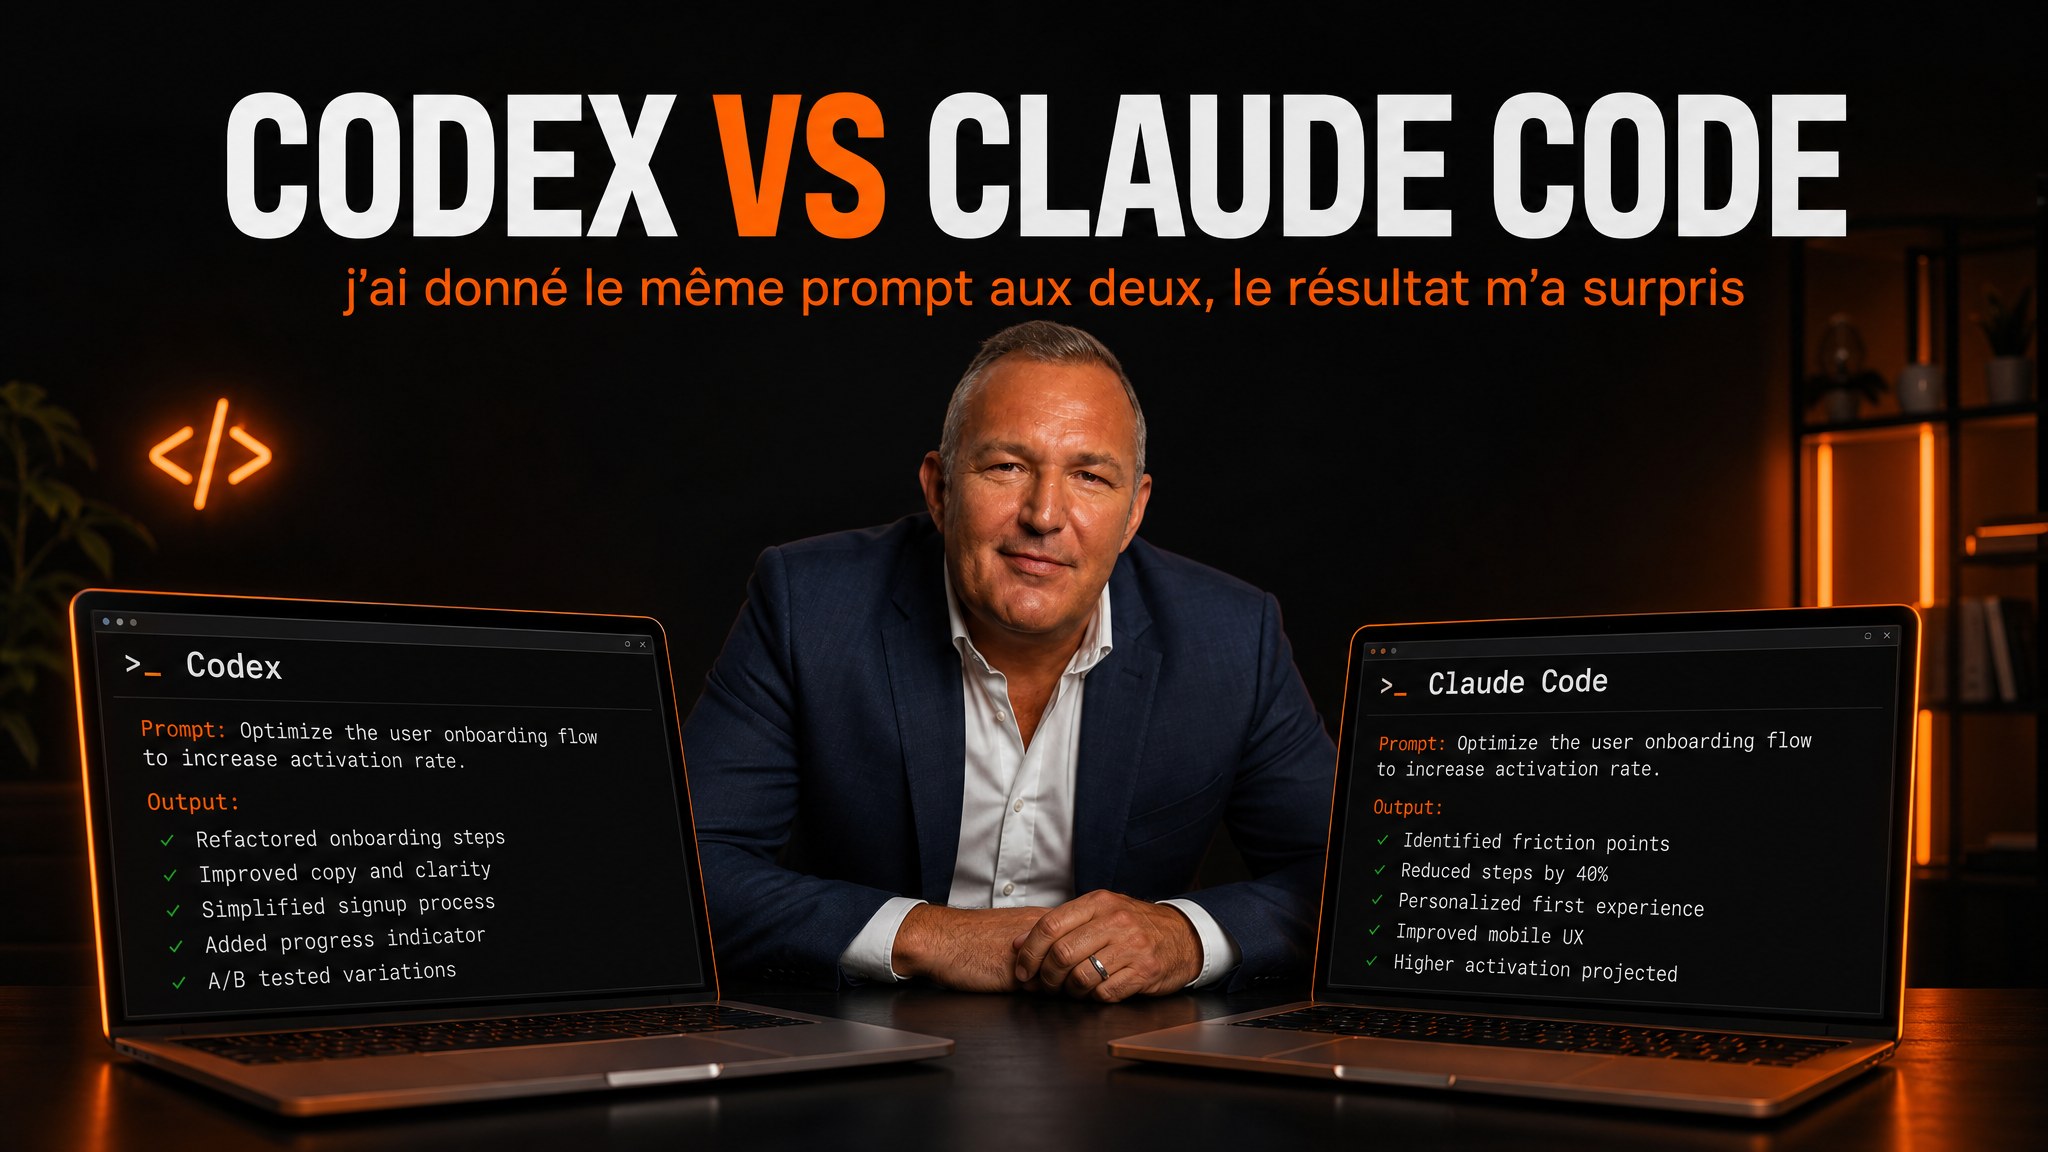
5 hours and $832. Second result: 61 hours and $3,000. Same prompt, same goal, two AI coding tools. The difference isn't 10%. It's 3,000%.
I sent Codex and Claude Code on the same mission: build a production-ready Typeform clone. Identical brief, one constraint, don't stop until the app is genuinely finished. No prototype. No "it works-ish." The real thing.
The result surprised me. And more importantly, it taught me something concrete about how these two systems actually work.
The duel: same prompt, two methods
The prompt sent to both agents was identical. A structured /goal across three phases: research, build, verify. The objective: a fully functional form builder app with authentication, conditional logic, themes, webhooks, and a results dashboard.
The final instruction was clear: "Don't stop at a prototype. Keep researching, building, testing, breaking, fixing, and retesting until the app is genuinely complete."
Two agents. Two radically different approaches.
| Metric | Claude Code | Codex |
|---|---|---|
| Cost | ~$832 | ~$3,000 |
| Time | 5.5 hours | 61 hours (2.5 days) |
| Sub-agents | 35 | 126 |
| Output tokens | 2 million | 11 million |
| Unit tests | 296 | 2,300 |
| Browser tests | 102 | 391 |
When Claude Code told me "it's done," Codex had been running for nearly a day and a half. I almost thought there was a bug.
What Claude Code nailed, the finesse
Claude Code built "Formora." The landing page is rough, you can tell the model didn't spend much energy on frontend design. But once you enter the app, the logic is there.
Form creation is intuitive. You choose a mode (conversational or stacked), define questions one by one, wire up conditional logic. The creation wizard genuinely feels like a Typeform clone. Field types are complete: short text, long text, email, phone, website, NPS, opinion scale, ranking, file upload.
Scoop: Claude Code used Opus 4.8 as the main orchestrator, even though I started the session on Fable 5. The model probably triggered a safety mechanism and degraded orchestration to a more conservative model. Result: Fable 5 did the heavy lifting, Opus 4.8 directed. Natural routing, not programmed.
Publication actually works. You generate a link, open the form, fill it out, results appear in the dashboard. It's not perfect, there are question numbering bugs, a missing logout button, but it's usable.
What struck me: the agent knew how to say no. It built 135 features instead of 150. It prioritized what created user value over checking a technical box. That's rare.
What Codex nailed, the brute force
Codex built "Realform." The landing page is clean, well-structured, with real effort on visual UX. The sections flow, the design is cohesive. Show this to someone and they won't guess it's AI-generated (well, almost).
But once you enter the admin panel, it's overload. Too many buttons, too many variables, too many options. The interface is technically impressive but overwhelming for an end user. It's the "I built everything, so I'll show everything" syndrome.
Where Codex shines: the backend architecture. Immutable revisions, offline recovery, concurrency handling, migration safety. The kind of stuff you don't see in the UI but matters when you deploy to production.
And the tests. 2,300 unit tests, 391 browser tests, cross-browser testing, mobile testing. Codex tested on Chrome, Firefox, Safari, Edge, in responsive mode, in degraded mode. It's a level above what Claude Code did.
The problem: it took 61 hours and $3,000 to get there. That's 11x more expensive and 6.6x slower.
The real problem: the prompt isn't neutral
Here's the trap we all fall into. We think "same prompt = same playing field." It's not.
Claude Code works better with a strategic brief: "here's the goal, here's what the output should contain, here's when you stop." The model interprets, explores, makes creative decisions. It acts like a technical co-founder.
Codex works better with an execution plan: step 1, step 2, step 3. The model is obedient, methodical, exhaustive. It doesn't stop until the checklist is complete, even if some items don't add real value.
My prompt looked like a strategic brief. Result: Claude Code interpreted the intent, Codex followed the instructions literally and overheated.
If I'd given a detailed 10-step plan, Codex would probably have been more efficient. The prompt format isn't neutral, it favors one model over the other.
The bugs, because there are always bugs
Both have bugs. It's inevitable when an agent builds a complete application in a few hours.
Claude Code (Formora):
- Question numbering doesn't update (all show "1")
- Logout button inaccessible in settings
- Design theme doesn't apply visually
- "Image preview unavailable" on upload
Codex (Realform):
- UI variables in permanent overload (user confusion)
- Color theme doesn't change anything visually
- No real authentication (demo workspace only)
- Confirmation popup positioned in the wrong place
Scoop: even with 2,300 unit tests and 391 browser tests, Codex didn't catch all UX bugs. Automated tests don't replace a human clicking around. It's like testing a restaurant by checking if the forks are clean, it doesn't tell you if the food is good.
When to use what, the practical guide
The question isn't "which is better." It's "which is better for what."
Use Claude Code when you have:
- A fuzzy goal but a clear vision of the expected result
- Speed needs (a functional prototype in half a day)
- A project where UX matters more than backend architecture
- A tight budget (under $1,000 for a complete sprint)
Use Codex when you have:
- A detailed execution plan with precise steps
- Exhaustive testing needs (cross-browser, mobile, edge cases)
- A project where backend architecture and reliability matter most
- A substantial budget and time (several days)
The winning approach: combine them. Claude Code for the design and initial build phase. Codex for security auditing, testing, and hardening. That's exactly what I'm doing right now, and the Codex Plugin for Claude Code (the adversarial review) has become indispensable in my workflow.
What this changes for you
If you're using AI coding agents to build applications, stop believing one tool does it all. It's like asking the same worker to design your house, build it, and inspect it. They'll be good at one of those three tasks, not all three.
Expertise is no longer in choosing the best model. It's in the ability to distribute the right work to the right tool.
5 hours and $832 versus 61 hours and $3,000. The same prompt. Two results that complement each other. Next time you launch an AI coding agent, ask yourself: am I giving a strategic brief or an execution plan? The answer will determine which model you should use.
Take action: your Express AI Audit (45 min)
45 minutes with an AI expert to evaluate your operations, identify productivity gains and map your first high-ROI AI agents.
Designed for SME leaders (10 to 100 staff) · No commitment · 100% IP ownership
Deploy AI Agents in your SME with an External CAIO
Get an outsourced AI Director 1 to 10 days per month to audit, automate your workflows and train your teams.
Stay ahead of AI Innovations
Every week, get a curated selection of our latest articles, case studies, and actionable AI insights directly in your inbox. No spam, 100% value.
Fractional AI Director locations